Scrape Magic
Scrape Magic is a lightweight AI extraction tool that extracts structured fields from unstructured web pages and documents by accepting natural-language field descriptions rather than requiring CSS/XPath selectors or maintained parsers.
Scrape Magic is a lightweight AI extraction tool that extracts structured fields from unstructured web pages and documents by accepting natural-language field descriptions rather than requiring CSS/XPath selectors or maintained parsers.
Published Jul 14, 2026
No public roadmap was found.
Not documented. Organizations should assume the product is optimized for low-to-moderate volume extraction until proven otherwise.
A limitation in this research is Scrape Magic's minimal footprint on major B2B review sites:
This absence is not proof of poor quality, but it reduces confidence for buyers who rely on validated third-party feedback.
No prominent Reddit or Hacker News discussion surfaced that was clearly about Scrape Magic.
The vendor claims the product can "mimic human-level understanding" and that the experience feels like asking a person to find requested information. These are vendor statements; no independent benchmarks, accuracy metrics, or methodology were published.
Because credible user reviews for this specific product are not available, selection and churn drivers are inferred from similar tools:
No formal Scrape Magic case studies were found on the official domain during this research.
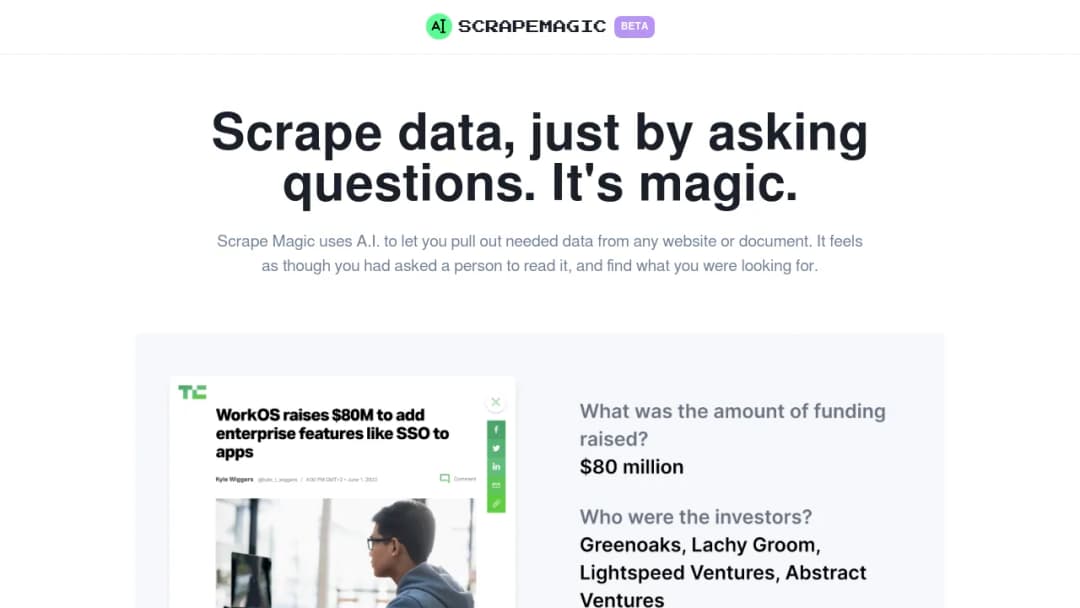
The site includes a demo-style example using a funding article and extracting fields such as funding amount and investors.
Critical evaluation:
Get a comprehensive analysis of Scrape Magic including market position, competitive landscape, adoption trends, and peer benchmarks.
Download full report →Scrape Magic is likely not suitable when:
Scrape Magic is a lightweight AI extraction tool that converts unstructured web pages and documents into structured fields by describing desired fields rather than requiring CSS/XPath selectors or maintained parsers. The site presents an LLM-style semantic extraction approach rather than deterministic scraping rules. Publicly visible features include:
Based on homepage examples (fundraising article parsing, investor lists, founder extraction), Scrape Magic appears targeted at:
Positioning emphasizes AI document/page understanding rather than high-throughput web scraping infrastructure. The product is not presented as a proxy/CAPTCHA bypass platform.